

Does an AI model use its entire "brain" every time you ask a question?
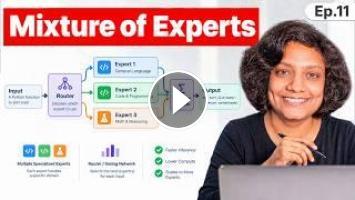
The answer is no. Modern Large Language Models use a powerful technique called Mixture of Experts (MoE) to activate only the parts of the model needed for a specific task.
In this video, you'll learn how Mixture of Experts architecture allows AI systems with hundreds of billions or even trillions of parameters to run efficiently without using the entire model for every request.
In this video, you'll learn:
Why massive AI models are expensive to run
What Mixture of Experts (MoE) architecture is
How MoE replaces one huge Feed Forward Network with specialized experts
How the gating network routes requests to the right experts
How AI selects experts for coding, language, math, and other tasks
Why trillion-parameter models only activate a fraction of their parameters
How MoE improves AI speed, cost, and scalability
Understanding MoE is essential for anyone interested in Large Language Models, Generative AI, AI Engineering, and the future of scalable Artificial Intelligence.
Subscribe for more deep dives into Transformers, LLM architecture, ChatGPT, and modern AI systems.
Want to work with me?
Brand, sponsorship & business inquiries: contact@thecoudgirl.dev
- Категория
- Бесплатные курсы
Комментариев нет.
Следующее
Auto
-
01:08

The most efficient way to create faceless youtube videos in any niche #facelessyoutube #aivideo
-
00:08
I help female online experts and coaches to automate their sales, ditch sales calls, and stop
-
01:21
Mixture & Allegation Complete Chapter With Tricks
-
23:47
Inside a Hyper-Tax-Efficient Retirement Plan: Roth Is Only Step One
-
00:06
I help female online experts and coaches to automate their sales, ditch sales calls, and stop
-
03:18
Can AI Really Think? Reasoning Models Explained
-
35:51
Local AI models explained: How to run a fleet of Mac Studios and GPUs at home
-
12:51
Libra! WOW! YES!! WOW!!! HUGE SHIFT IN YOUR FINANCES! Fast path or slow path?
-
31:01
+23% In 2 Days: SpaceX Stock Surges, "Experts" In Shambles
-
1:06:48
YouTube Automation Video Editing Full Lecture Learn Pro Editing Like Experts
-
05:33

ЗАРАБОТОК В ИНТЕРНЕТЕ | КРУТАЯ СХЕМА | FUNPAY
-
08:12

Пассивный Заработок 1000Р в День в Интернете на Телефоне Без Вложений
-
06:43
Как ЗАРАБОТАТЬ ШКОЛЬНИКУ в ИНТЕРНЕТЕ? Самые Легкие Способы Заработка
-
07:05

ЗАРАБОТОК В ИНТЕРНЕТЕ 2023 | Реальный заработок в интернете с вложением | Как заработать в интернете
-
05:49

ЗАРАБОТОК В ИНТЕРНЕТЕ 2023 | Реальный Заработок В Интернете С Вложением. Как Заработать В Интернете?
-
04:28

Схема заработка 2023 ! Зарабатываем в интернете онлайн сидя дома ! Заработок денег ! Деньги легко !
-
05:33

ЗАРАБОТОК В ИНТЕРНЕТЕ | КРУТАЯ СХЕМА | FUNPAY
-
06:43

Как ЗАРАБОТАТЬ ШКОЛЬНИКУ в ИНТЕРНЕТЕ? Самые Легкие Способы Заработка
-
14:53

Показываю Как Зарабатывать Деньги - Заработок В Интернете 2023 Рабочая Схема Для Заработка
-
14:12

Большой Заработок В Интернете С Выводом Рабочая Схема Заработка
 Загрузка...